Merge Google Drive PDF Files and Save Them Back using Google Apps Script and PDF.co
In this short step-by-step guide and demo, we’ll review how to merge PDF files in Google Drive and save them back to Google Drive using Google Apps Script and PDF.co.
How to Merge PDF Files in Google Drive – Inputs
We will start with a Google Drive folder, which contains two PDF files and a Spreadsheet.
Google spreadsheet designed as shown in the below screenshot.
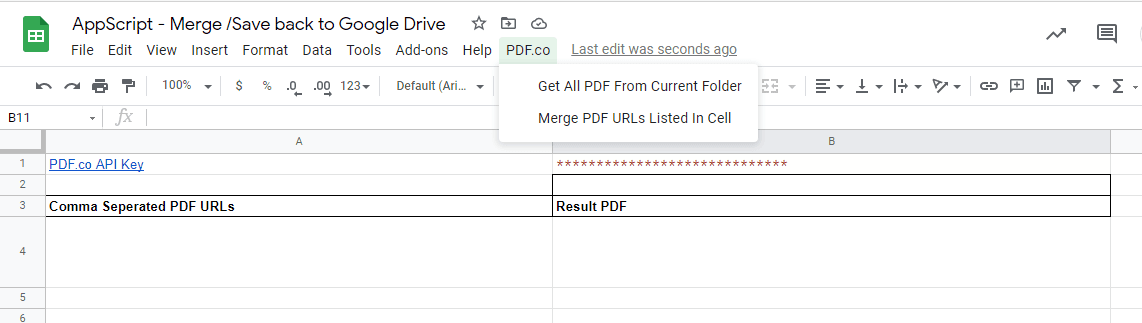
As we observe, In the first row we have a label for PDF.co API Key and in the adjacent cell, we’ll put PDF.co API key. You can obtain your PDF.co API key from signing up at PDF.co at this URL.
How to Combine PDF Files in Google Drive – Output Demo
Here, we have created a new menu named “PDF.co”. Inside that first sub-menu “Get all PDF from Current Folder” gets all PDF files from the same folder as the spreadsheet, and puts them in comma-separated format into a cell.
To merge PDF files we’ll be using PDF.co API. As PDF.co service requires publicly accessible PDF files, we’ll be also making PDF files publicly accessible, and get that download URL specifically.
The second Submenu “Merge PDF URLs Listed In Cell”, calls PDF.co and merges all PDF file URLs. It’ll update the result PDF URL to the output cell, and also store the actual file to drive location.
Combining PDF Files Google Drive – Source Code
/**
 * Initial Declaration and References
 */
// Get the active spreadsheet and the active sheet
ss = SpreadsheetApp.getActiveSpreadsheet();
ssid = ss.getId();

// Look in the same folder the sheet exists in. For example, if this template is in
// My Drive, it will return all of the files in My Drive.
var ssparents = DriveApp.getFileById(ssid).getParents();

// Loop through all the files and add the values to the spreadsheet.
var folder = ssparents.next();


/**
 * Add PDF.co Menus in Google Spreadsheet
 */
function onOpen() {
  var menuItems = [
    {name: 'Get All PDF From Current Folder', functionName: 'getPDFFilesFromCurFolder'},
    {name: 'Merge PDF URLs Listed In Cell', functionName: 'mergePDFDocuments'}
  ];
  ss.addMenu('PDF.co', menuItems);
}


/**
 * Get all PDF files from current folder
 */
function getPDFFilesFromCurFolder() {
  ss.getRange("A4").clearContent();

  const files = folder.getFiles();
  const urls = [];
  const apiKey = String(getPDFcoApiKey() || "").trim();

  if (!apiKey) {
    throw new Error("Configure your PDF.co API key first.");
  }

  while (files.hasNext()) {
    const file = files.next();
    const name = file.getName();
    const lowerName = name.toLowerCase();

    if (!lowerName.endsWith(".pdf")) continue;
    if (["result", "result.pdf"].includes(lowerName)) continue;

    const prepared = UrlFetchApp.fetch(
      "https://api.pdf.co/v1/file/upload/get-presigned-url" +
        "?contenttype=application/octet-stream&name=" +
        encodeURIComponent(name),
      {
        method: "get",
        headers: { "x-api-key": apiKey },
        muteHttpExceptions: true
      }
    );

    let upload;

    try {
      upload = JSON.parse(prepared.getContentText());
    } catch (error) {
      throw new Error("Invalid upload preparation response for " + name);
    }

    if (
      prepared.getResponseCode() !== 200 ||
      !upload ||
      upload.error ||
      !upload.presignedUrl ||
      !upload.url
    ) {
      throw new Error(
        (upload && upload.message) ||
          "Could not prepare upload for " + name
      );
    }

    const sent = UrlFetchApp.fetch(upload.presignedUrl, {
      method: "put",
      contentType: "application/octet-stream",
      payload: file.getBlob().getBytes(),
      muteHttpExceptions: true
    });

    const status = sent.getResponseCode();

    if (status < 200 || status >= 300) {
      throw new Error("Upload failed for " + name + ": HTTP " + status);
    }

    urls.push(upload.url);
  }

  if (urls.length < 2) {
    throw new Error("Provide at least two source PDFs in the input folder.");
  }

  ss.getRange("A4").setValue(urls.join(","));
}

function getPDFcoApiKey(){
  // Get PDF.co API Key Cell
  let pdfCoAPIKeyCell = ss.getRange("B1");

  return pdfCoAPIKeyCell.getValue();
}

/**
 * Function which merges documents using PDF.co
 */
function mergePDFDocuments() {

  // Get Cells for Input/Output
  let pdfUrlCell = ss.getRange("A4");
  let resultUrlCell =  ss.getRange("B4");

  let pdfUrl = pdfUrlCell.getValue();

  // Prepare Payload
  const data = {
    "async": true, // As we have large volumn of PDF files, Enabling async mode
    "name": "result",
    "url": pdfUrl
  };

  // Prepare Request Options
  const options = {
    'method' : 'post',
    'contentType': 'application/json',
    'headers': {
      "x-api-key": getPDFcoApiKey()
    },
    // Convert the JavaScript object to a JSON string.
    'payload' : JSON.stringify(data)
  };

  // Get Response
  // https://developers.google.com/apps-script/reference/url-fetch
  const resp = UrlFetchApp.fetch('https://api.pdf.co/v1/pdf/merge', options);

  // Response Json
  const respJson = JSON.parse(resp.getContentText());

  if(respJson.error){
    console.error(respJson.message);
  }
  else{

    // Job Success Callback
    const successCallbackFn = function(){
      // Upload file to Google Drive
      uploadFile(respJson.url);

      // Update Cell with result URL
      resultUrlCell.setValue(respJson.url);
    }

    // Check PDF.co Job Status
    checkPDFcoJobStatus(respJson.jobId, successCallbackFn);
  }
}

/**
 * Checks PDF.co Job Status
 */
function checkPDFcoJobStatus(jobId, successCallbackFn){
  // Prepare Payload
  const data = {
    "jobid": jobId
  };

 // Prepare Request Options
  const options = {
    'method' : 'post',
    'contentType': 'application/json',
    'headers': {
      "x-api-key": getPDFcoApiKey()
    },
    // Convert the JavaScript object to a JSON string.
    'payload' : JSON.stringify(data)
  };

  // Get Response
  // https://developers.google.com/apps-script/reference/url-fetch
  const resp = UrlFetchApp.fetch('https://api.pdf.co/v1/job/check', options);

  // Response Json
  const respJson = JSON.parse(resp.getContentText());


  if(respJson.status === "working"){
    // Pause for 3 seconds
    Utilities.sleep(3 * 1000);

    // And check Job again
    checkPDFcoJobStatus(jobId, successCallbackFn);
  }
  else if(respJson.status == "success"){
    // Invoke Success Callback Function
    successCallbackFn();
  }
  else {
    console.error(`Job Failed with status ${respJson.status}`);
  }
}

/**
 * Save file URL to specific location
 */
function uploadFile(fileUrl) {
  var fileContent = UrlFetchApp.fetch(fileUrl).getBlob();
  folder.createFile(fileContent);
}
This script uses the built-in DriveApp and UrlFetchApp services. Authorize the requested access when you first run it. No Advanced Drive service setup or anonymous-sharing permission is required.
The script reads source PDFs through your authorized Google Drive access and uploads temporary copies to PDF.co. It does not change the original files’ sharing permissions.
Run the merge promptly after collecting the URLs because the uploaded copies expire. The filter excludes result.pdf, the example’s output filename. If you change that filename, update the filter or save generated PDFs outside the input folder.
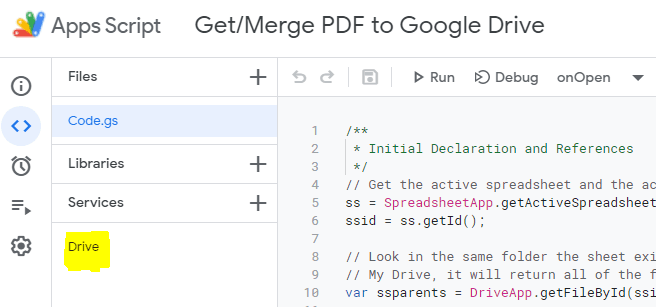
At the beginning of the source code, we’re declaring all necessary references such as the current spreadsheet, current Google Drive folder, etc.
Next, we’re writing code to add a menu on the onOpen event. This event is called every time Google Spreadsheet is opened.
The collection step uploads source PDFs from Google Drive to PDF.co’s temporary storage and writes their URLs into cell A4 for the merge request. The original Drive files retain their sharing settings. Check that A4 contains only the intended source URLs before running Merge PDF URLs Listed In Cell.
I hope this article is useful to you. Thank you!
Video Guide
Related Tutorials