Extract Text from Scanned PDF in JavaScript using PDF.co Web API
This tutorial extracts text from a scanned PDF using PDF.co and JavaScript. The example uses an asynchronous PDF-to-text request, so the initial response identifies a background job rather than a completed text file.
Wait for Completion, Then Check the Text
Keep the job ID and check its status with a delay between requests and a limit on the total waiting time. Continue checking while the status is working, and download the TXT output only after success. Stop on failed or aborted. Network failures and processing limits still need handling.
Compare the extracted text with the scan, particularly identifiers, dates and amounts. A successful job means processing finished; it does not guarantee that OCR recognized every character correctly.
Step 1: Source Code
Copy the JavaScript sample code provided here and open it in your favorite editor.
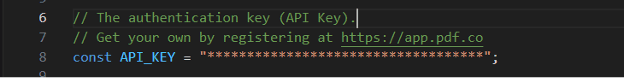
Step 2: Add Your PDF.co API Key
Add your API key in the appropriate section of the code (line 8). You can retrieve your API key from the PDF.co Dashboard.
Step 3: Provide the Scanned PDF Source URL
Specify the URL of the scanned PDF to be processed in line 11.

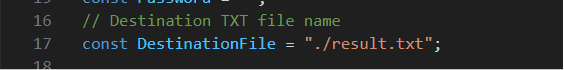
Step 4: Destination File
Define the output destination for the extracted text in line 17.
How It Works
- Initiating an Asynchronous Conversion:
- The code sends a request to the PDF.co API to start a PDF-to-TXT conversion with the
asyncoption set totrueto enable asynchronous processing. - Retain the returned
jobId. Check it by sendingPOST https://api.pdf.co/v1/job/checkwith{"jobid":"YOUR_JOB_ID"}as the JSON body and the same PDF.co API key in thex-api-keyheader.
- The code sends a request to the PDF.co API to start a PDF-to-TXT conversion with the
- Checking Job Status:
- The code uses the job ID to periodically query the job's status by sending requests to the API.
- Once the status changes to "
success", it indicates that the conversion process is complete, and the result file is ready for download.
- Downloading the Result:
- After the conversion is successfully completed, the code retrieves the converted TXT file from the provided URL and saves it to the specified location on the local system.
In this tutorial, you’ve learned how to extract text from scanned PDFs in Asynchronous Mode using PDF.co Web API. By leveraging this mode, your application remains responsive and efficient while processing large or complex files.
Related Tutorials