If you are getting error messages like “Too many Requests” and “Access Denied” while providing the input URL, you can add a cache to enable built-in caching functionality.
Read PDF Metadata and Document Properties in JavaScript
12 Minutes Read
This tutorial uses PDF.co’s /v1/pdf/info endpoint to inspect document properties, including page count, metadata and security permissions. Use this information to check a PDF before choosing the next processing operation. This endpoint does not extract invoice line items or convert the document into plain text.
For interactive form field names and values, use /v1/pdf/info/fields and its documented response structure. Choose the endpoint that returns the information your application needs.
Benefits of Asynchronous Processing
Asynchronous processing enables non-blocking operations, meaning that you can send a request for PDF extraction and continue with other tasks without having to wait for the operation to complete. This leads to:
- Improved Application Performance: Asynchronous processing allows your application to handle multiple requests simultaneously, improving user experience by reducing wait times.
- Scalability: By using asynchronous operations, your application can scale more effectively, handling large numbers of requests without overloading the server or blocking other processes.
- Efficiency in Resource Management: With asynchronous tasks, resources are utilized more efficiently as the application does not have to wait for one task to complete before moving on to the next.
For more details on asynchronous processing, refer to the PDF.co Documentation on Async and Sync Mode.
Features of PDF Info Reader API Endpoint
PDF Info returns the document information defined by the selected endpoint. Inspect the returned properties to check the source PDF and decide how to process it. Metadata and security permissions describe the document; they are not an extraction of its visible text, tables or images.
To retrieve interactive form field names, types and values, use the separate /v1/pdf/info/fields endpoint. For a manual check, open your PDF in the PDF Inspector.
One of the best features of the PDF.co Web API is that it provides high security for its users. The API maintains security by transmitting your documents and data files via encrypted connections. You can learn more about the PDF.co API security here.
Endpoint Parameters
Following is a comprehensive explanation of the available parameters of the PDF Info Reader API.
url: It is a required parameter that contains the link to the source file. It provides the URL of the input PDF document from which you want to extract information. The PDF.co platform supports any publicly accessible URL, including those from Dropbox, Google Drive, and the built-in file storage of PDF.co. You can encrypt or decrypt any input or output data file using the user-controlled data encryption functionality.
httpusername: It is an optional parameter that takes the http auth user name if it is necessary to access the source URL.httppassword: It is an optional parameter that takes the http auth password if it is required to access the source file.async: When set totrue, the process runs asynchronously, and the response will include a job ID and a status URL to check the operation's progress. You can poll the status URL or use webhooks to get notified when the task is complete..profiles: It is an optional parameter that must be a string. You can set additional customized configurations for file tuning and extra options using this parameter.
The JavaScript example requests document properties from /v1/pdf/info. Provide your PDF.co API key and a source PDF URL that PDF.co can access.
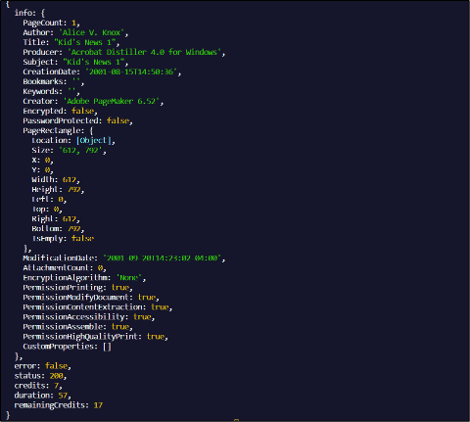
The result contains document information such as page count, author, title and security permissions. It does not reveal the PDF’s password. If the source PDF requires a password, supply it through the request’s password parameter.
Read PDF Document Properties in JavaScript
The following source code shows you how to extract information from a sample PDF document using the PDF.co Info Reader API. The sample code in Javascript shows how to gather relevant information from a PDF sample document. You can upload your respective documents or provide a link to them in the URL parameter to collect valuable data. You can have information such as text fields, page count, permissions, checkboxes, and more.
The code contains a sample PDF form as an example here. You must provide a generated API key by logging into the PDF.co platform login and the pdf file URL in the API request for the API to work. Moreover, the PDF.co API returns the resulting output of the provided file URL from which you can separate required information such as the author, page number, password, permissions, bookmarks, and information regarding the PDF content.
Sample Code Snippet for PDF Extraction
Following is an example code to extract information from a PDF form using PDF.co Web API:
Code Sample: Here
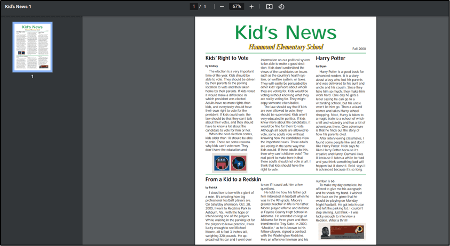
Source File
Below is the screenshot of the source file used for this example.
Output of Extracted PDF
Below is the screenshot of the output provided after the execution of the above sample code.
Sample Code Walkthrough
Following is a sample guide to explain the working of sample code for extracting information using the Info Reader API endpoint:
- You must import the necessary packages to send API requests. The
requireparameter represents all the crucial modules. In this scenario, the essential package used for making HTTP requests isaxios, a promise-based HTTP client for the browser and Node.js. Unlike therequestmodule, which is used for making HTTP calls in older versions,axiosis now preferred for its simplicity and better support for asynchronous operations. Thepathpackage is still required if file path manipulation is needed in the application. - After logging in to the PDF.co website, you can obtain your API key to access the Web API. You can't send a direct request, so you will need to use this specific API key as an access token in the header for authentication.
- Since you might have to use the code several times, the best approach is to use the API key in variable declaration. This approach allows you to change the variable and edit the complete code file without changing anything in the actual code.
- The next step is to declare and initialize the source file and query path variables for the document to extract critical information from it. The query path contains the information of the relevant API endpoint you want to utilize in the scenario.
- Build the JSON request body. Set
urlto the source PDF URL andasynctotruefor this asynchronous example. If the PDF is password-protected, include itspassword. This request reads document properties; it does not add text or fill form fields. - You should set the
asyncparameter totrueto enable asynchronous processing, ensuring smoother and more efficient operation. - You must declare a variable to provide API options such as API endpoint URL, method, and headers. The code contains “reqOptions” for initializing such information in this example.
- Send the request and inspect both the HTTP response and the API response body. For an asynchronous request, retain the job ID and check that job’s status. Continue polling only while it is
working, and process the result aftersuccess. Stop onfailedoraborted, and set a polling deadline. Do not repeatedly submit the operation while the original job is running. If it fails, inspect the error and correct the input or configuration before retrying. After success, confirm that the result contains the document properties your application requires.
Related Tutorials